Ask Every AI Model At Once, Keep The Best
Beam one prompt to several AI models, compare their answers, and keep the best one.
The full version connects to any OpenAI-compatible endpoint
- OpenAI-compatible APIs
- Self-hosted vLLM
- Ollama
- LM Studio
- Open-weight models
About Helm
Helm is a multi-model AI workspace designed and engineered by Randy See. Instead of trusting one model, you beam a prompt across several, compare their answers side by side, and merge the best parts into one reply, with every chat saved in your own browser.


Our Features
What Makes Helm Different
Everything you need to put several models to work on one question, and keep the answer you trust.
One prompt, every model
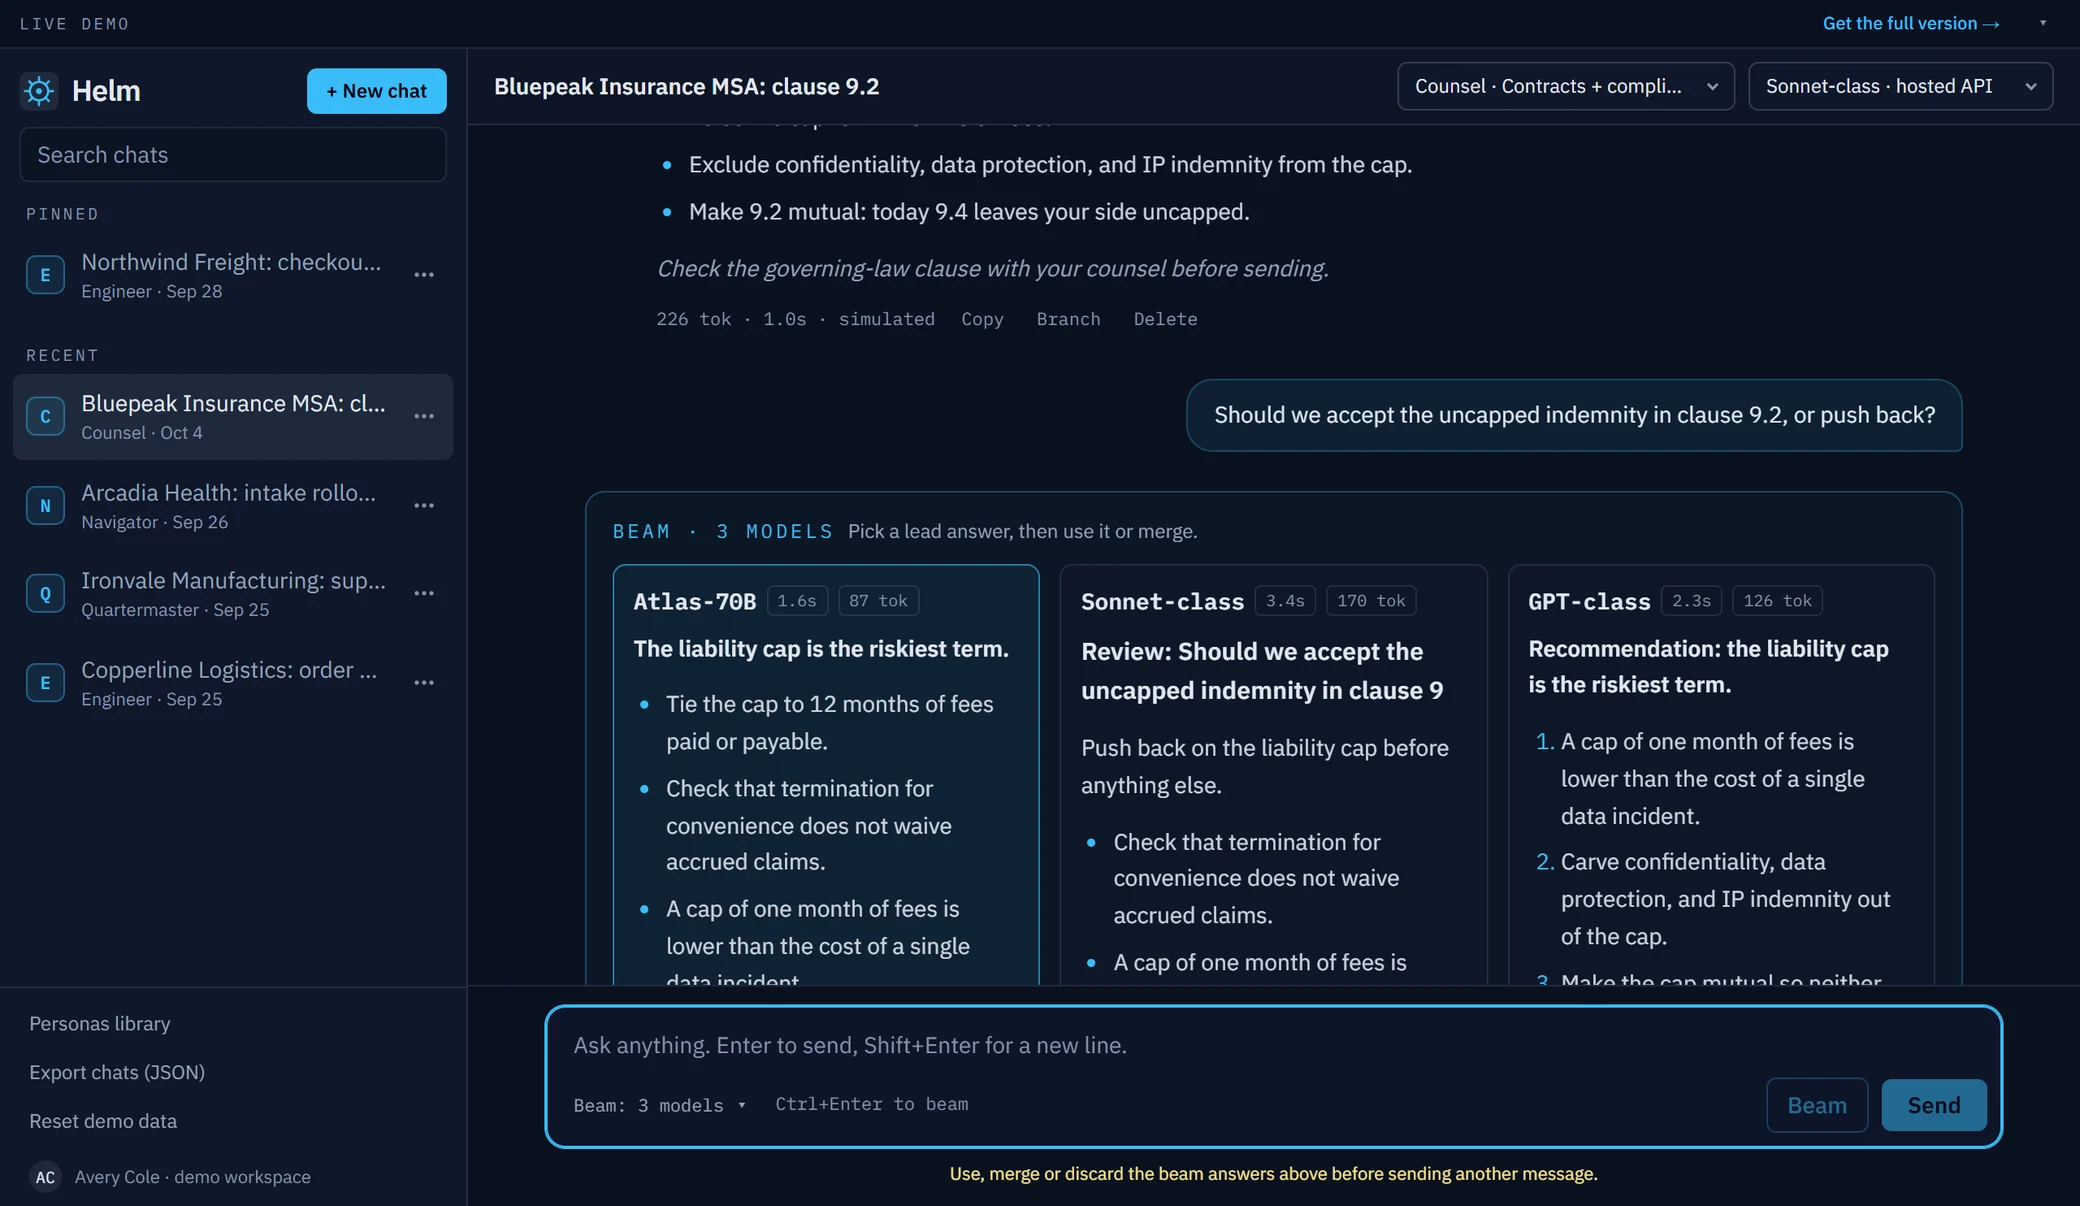
Beam a prompt to two, three or four models at once, then keep the best answer or merge the strongest points of each into one reply.
Made for every model.
Four simulated models in the demo. The full version wires in yours.
Personas on demand
Six built-in specialists, from Engineer to Counsel, plus any you create. Switch one in mid-thread.
Watch every answer stream in.
Each model streams into its own column with its timing and token count, so you see at a glance who answered fast and who went deep.
By the numbers
Designed & Engineered by Randy See.
- 4Models in the demo
- 6Built-in personas, plus yours
- 5Seeded chats to explore
- 0Sign-ups or API keys
How it works
How Helm Works
Open the real app, put it to work on a real question, then talk to Randy See about yours.
- Open the live demo
- Beam and merge
- Get the full version
Open Helm in your browser
The workspace loads with seeded chats, six personas and four simulated models. No install, no sign-up, no API keys.
Beam a question, then merge the answers
Send one prompt to several models, read them side by side, and keep one answer or merge the best of each into a single reply.
Get the full version from Randy See
Randy See wires in your models, adds your branding and sign-in, deploys it on your infrastructure and hands it over. No subscription.
Bring any model you run
Hosted APIs, self-hosted open weights, or a private gateway, wired in through your own backend so keys never touch a browser.
Advantage
Why Choose Helm?
A second opinion on every answer, without handing your chats to anyone.

Answers You Can Check
See where models agree before you act. Merge the best points into one reply.

Yours to Keep and Shape
Chats stay in your browser. The full version is handed over, with no seat fees.
Use cases
What Teams Put Helm To Work On
Each persona re-frames every answer for the job at hand. Switch one in mid-thread.
Checkout p99 doubled after a cache migration. Beam the rollback question to three models, compare their calls side by side, and merge the fix plan into one memo.
An MSA caps the vendor's liability at one month of fees. Run clause 9.2 past Counsel on several models and merge the carve-outs into one redline.
Separate evidence from inference before the board deck. Branch the analysis at the reply that matters and keep both versions in your chat list.
Turn a clinic's intake rollout into owners, milestones and the first step for this week, then beam the plan to a second model for the gaps.
Supplier lead times slipped again. Weigh costs, lead times and fallbacks across models, then keep the answer that gives you a plan B.
Seeded chats
Real Work, Already In The Demo
Open any of these chats in the live demo and keep going: beam it, branch it, merge it.

Ready to Put Several Models On Every Question?
Try Helm in your browser right now, then message Randy See on WhatsApp to get the full version built around your models.
Still Have Questions?
Message Randy See on WhatsApp and get your answer from the engineers who built Helm, not a sales queue.
FAQ’s